Qwen3.8-Flash-Next upgrades the model systematically along four aspects — attention, residual, embedding and optimization — improving model capability while further optimizing computational efficiency, model capacity and training stability:
• Attention: A GDN + QSA hybrid architecture. Gated DeltaNet (GDN) compresses the history efficiently; Qwen Sparse Attention (QSA) uses a compressed lightweight indexer to select the important context at micro-block granularity, substantially reducing the cost of attention on long sequences.
• Residual: Gated Residual (GR) widens the residual stream into 4 branches and controls reads and writes with a dynamic gate, strengthening cross-layer information flow and training stability.
• Embedding: N-gram Embedding looks up a table using the local context to scale model capacity with very little extra computation; the embedding table can be offloaded to host memory and overlapped with model computation through asynchronous prefetching.
• Optimization: The Muon optimizer is used, refined around orthogonalization accuracy, the division of labour between Muon and AdamW, and the splitting of fused parameters, with the scaling law refitted for the new architecture. (View Highlight)
Qwen3.8-Flash-Next features a 125B-parameter main model, supplemented by an additional 51B N-gram embeddings, with 6B parameters activated per token. Compared with Qwen3.7-Plus, Qwen3.8-Flash-Next substantially reduces both training and inference cost — training takes only about 1/9 as much, yet it delivers superior capabilities in coding and office tasks.
It natively supports 262,144 tokens of context and is extensible to 1,000,000 tokens with YaRN. For more technical details on the architecture, training methodology, and experimental analysis of Qwen3.8-Flash-Next, please refer to the technical report in our GitHub repository. (View Highlight)
Qwen3.8-Flash-Next weights are now available on Hugging Face and ModelScope. The production version, with 1M context by default and official built-in tools, is served as Qwen3.8-Flash on QwenCloud, priced at 0.16 USD per million input tokens and 0.47 USD per million output tokens(API coming soon). (View Highlight)
In this release we are opening the weights of Qwen3.8-Flash-Next, a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4. It plays the same role that Qwen3-Next played for Qwen3.5: the hybrid Gated DeltaNet + Gated Attention design introduced at that time has since been used across the Qwen3.5, Qwen3.6, Qwen3.7 and Qwen3.8 series. We are again releasing the architectural changes early, so that the community can examine them before the full Qwen4 model family is built on top of them. (View Highlight)
Traditional Full Attention provides direct access to all previous tokens, but as the context grows longer, both computation and KV Cache memory-access costs increase substantially.
Following the architecture design introduced in Qwen3.5, Qwen3.8-Flash-Next adopts a GDN 1(https://qwen.ai/blog/#ref1) + Attention Hybrid architecture: three out of every four layers use Gated DeltaNet (GDN) to continuously compress historical information into a fixed-size state, while the remaining layer uses global Attention for precise retrieval of information across the full context. (View Highlight)
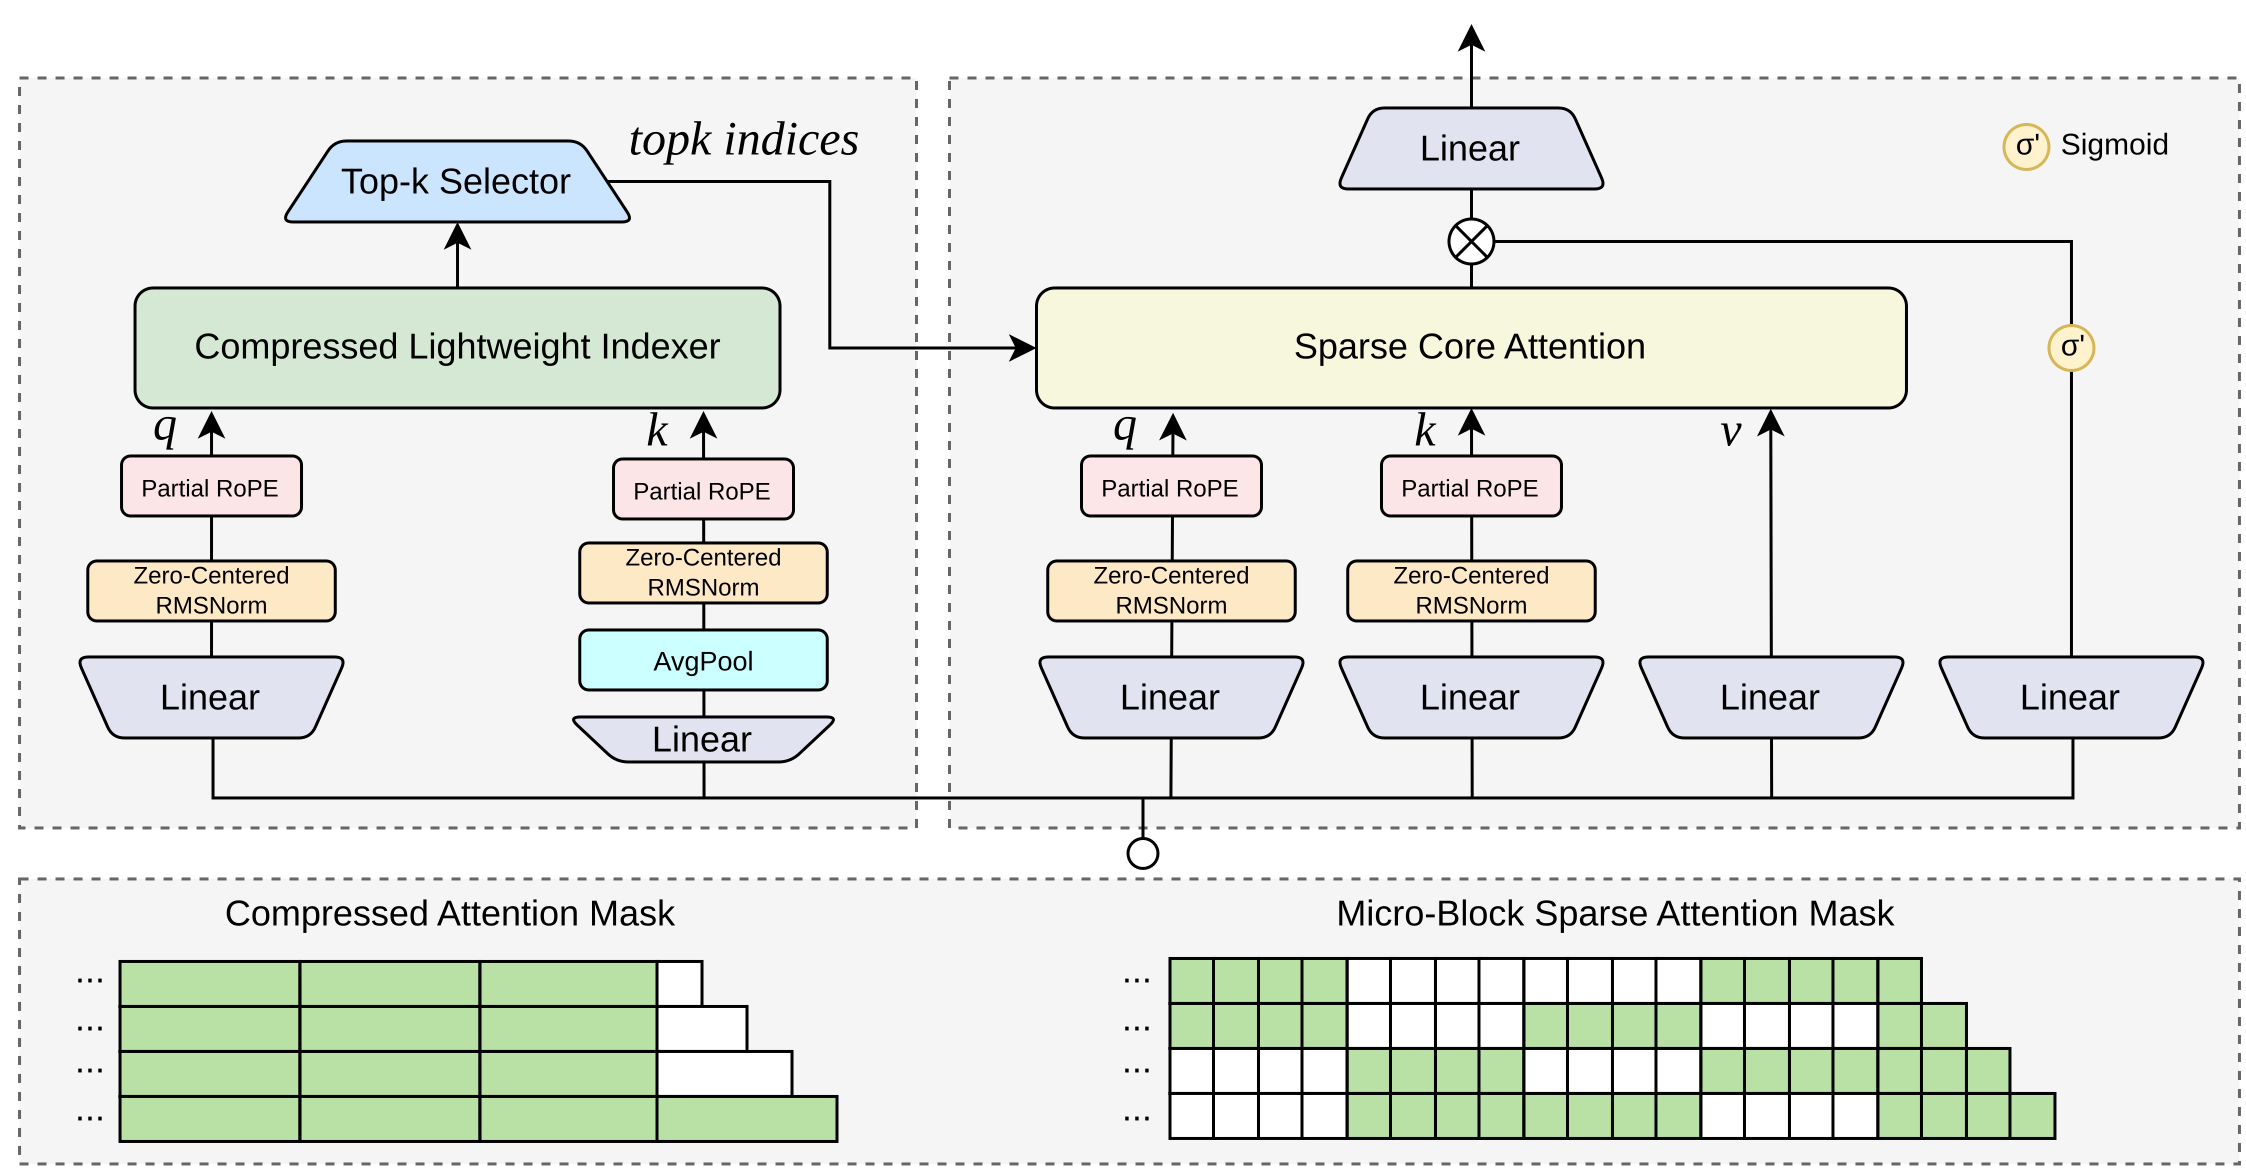
For global Attention, we further introduce Qwen Sparse Attention (QSA). Sparse Attention reduces long-sequence computation by attending only to important context. However, existing approaches such as DSA 2(https://qwen.ai/blog/#ref2) still rely on a token-level indexer to identify important positions; as the context grows, the indexer itself becomes a non-negligible source of computation.
QSA further compresses this process: a lightweight indexer first aggregates the sequence into micro-blocks, estimates context importance at the block level, and then selects the most relevant regions for Attention. This reduces not only the cost of Attention itself, but also the indexing overhead required to identify important context. Compared with approaches that share indices across layers 3(https://qwen.ai/blog/#ref3), QSA performs sequence compression independently within each layer, reducing its dependence on cross-layer Attention similarity and making it particularly well suited to Hybrid architectures where GDN and Attention layers are interleaved. (View Highlight)
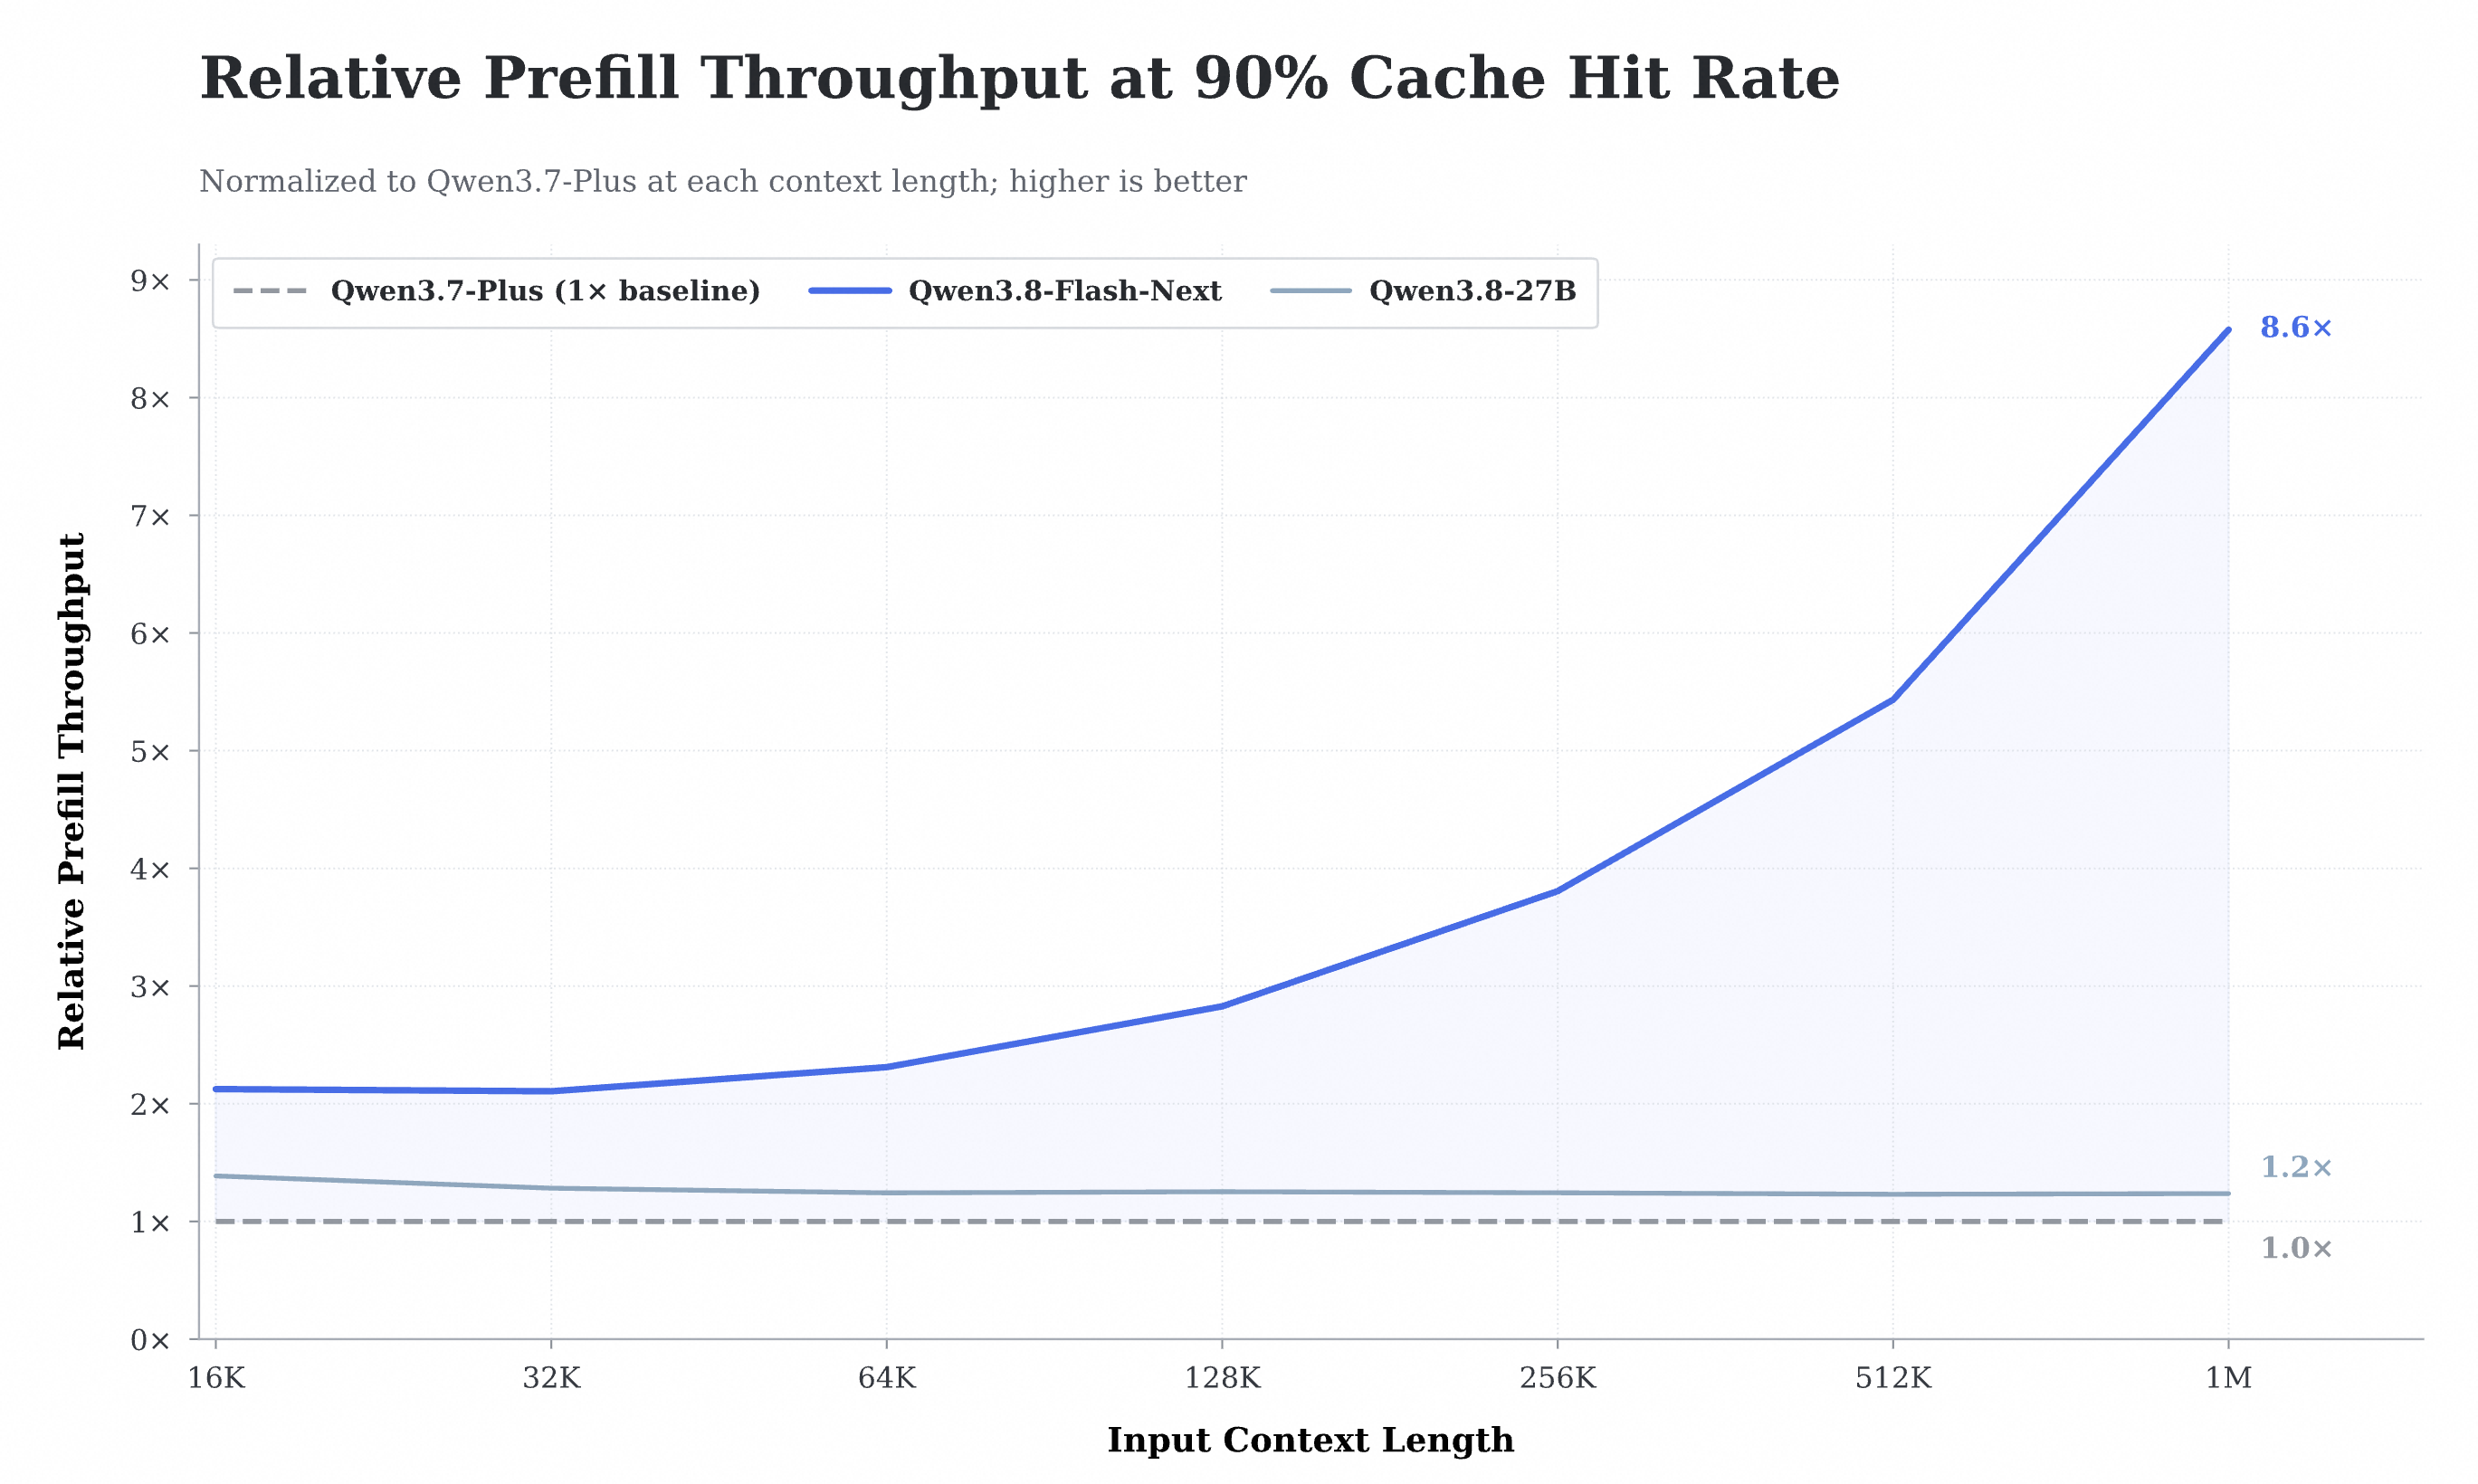
At 1M tokens, QSA’s Attention Kernel achieves up to 7.6× and 4.9× speedups in Prefill and Decode, respectively. In an experimental setup representative of online serving scenarios with high cache reuse (a 90% Prefix Cache hit rate), Qwen3.8-Flash-Next achieves 8.6× the Prefill throughput of Qwen3.7-Plus at a 1M-token context length. (View Highlight)
Gated Residual: More Paths for Information Flow#
In a traditional Transformer, all layers continuously read from and write to the same Residual Stream. As the network becomes deeper, early features are repeatedly mixed with later information, making important signals more likely to be gradually diluted. Gated Residual (GR) can be viewed as a combination of two ideas: it follows Hyper-Connection4(https://qwen.ai/blog/#ref4) in widening the residual stream into multiple branches, while incorporating the element-wise dynamic gating of GatedNorm5(https://qwen.ai/blog/#ref5) into the residual read. The original single residual stream is expanded into four parallel branches, allowing the model to dynamically determine how much information to read from each branch and how much to write back to each branch based on the current content.
This can be conceptualized as expanding a single information channel into multiple parallel pathways: some branches handle local information flow, while others preserve early information directly deep into the network layers. Empirical analysis also reveals that one of these branches naturally emerges as a long-range pathway connecting the first Attention layer to most of the middle and subsequent layers.
GR also further simplifies Hyper-Connection. Once the read and write operations are expressive enough, additional branch mixing yields no significant benefits and can thus be directly removed, thereby reducing memory access overhead and sources of instability. The Gate also effectively suppresses activation outliers and improves training stability. In addition, the Residual State supports FP8 storage, further reducing memory-access overhead. (View Highlight)
N-gram Embedding: Expanding Model Capacity at Low Cost#
Inspired by Per-Layer Embedding in Gemma 3n and works such as DeepSeek Engram 6(https://qwen.ai/blog/#ref6), we further introduce N-gram Embedding to scale model capacity beyond the parameters of the Transformer backbone.
A standard Embedding performs a lookup based on a single token. N-gram Embedding instead performs lookups using the local context formed by the current token and several preceding tokens, providing additional representations for common phrases and local patterns.
Its key advantage is that it can add a large number of parameters with almost no additional computation per token.
Qwen3.8-Flash-Next introduces an additional 51B N-gram Embedding parameters. Because lookup locations can be determined in advance, these parameters can be stored in Host Memory and asynchronously prefetched in parallel with model computation, without permanently occupying GPU memory.
The final model uses only a single N-gram Embedding layer near the beginning of the network, effectively adding a large-scale “local-pattern memory” at relatively low additional cost. (View Highlight)
Other Architecture Optimizations#
The remaining components follow the design established in Qwen3-Next and refined through the Qwen3.5–Qwen3.8 series.
• Ultra-sparse MoE: With global load balancing 8(https://qwen.ai/blog/#ref8), increasing total expert parameters while keeping the number of activated experts fixed steadily reduces training loss. Qwen3.8-Flash-Next therefore uses a large expert pool with a small number of routed experts per token, together with one shared expert.
• Multi-Token Prediction: The MTP module is trained with multiple steps, maintaining consistency between training and inference and thereby improving the acceptance rate of speculative decoding in real scenarios, while also enhancing the performance of the backbone. Its full-attention layers are replaced with QSA as well.
• Training stability: Zero-centered RMSNorm with weight decay applied to norm weights, the attention output gating mechanism 9(https://qwen.ai/blog/#ref9), and normalized MoE router initialization are retained. These designs make small-scale ablations more reliable and help large-scale training run smoothly. (View Highlight)
With 6B activated parameters, Qwen3.8-Flash-Next-Base achieves the best result on 8 of the 14 benchmarks, including MMLU-Pro, SuperGPQA, BBH, GSM8K, EvalPlus, SWEBench-Pretrain, MGSM and MMMLU, and remains close to Qwen3.7-Plus-Base on MMLU, MMLU-Redux, GPQA, MATH and MultiPL-E. The 51B N-gram embedding parameters are deterministically addressed and do not enter the per-token matrix-multiplication budget. (View Highlight)

 (View Highlight)
 (View Highlight)