Your team already runs more coding agents than you can name. Cursor sits in the IDE, Claude Code runs in the terminal, and someone on the platform team wired up Codex CLI. Two more developers are trying Gemini CLI and Pi. Each one carries its own key and bills its own account, and none of them answer to a shared policy. That is coding-agent sprawl, and it scales with your headcount: every developer you add makes it harder to say who spent what and who sent what. (View Highlight)
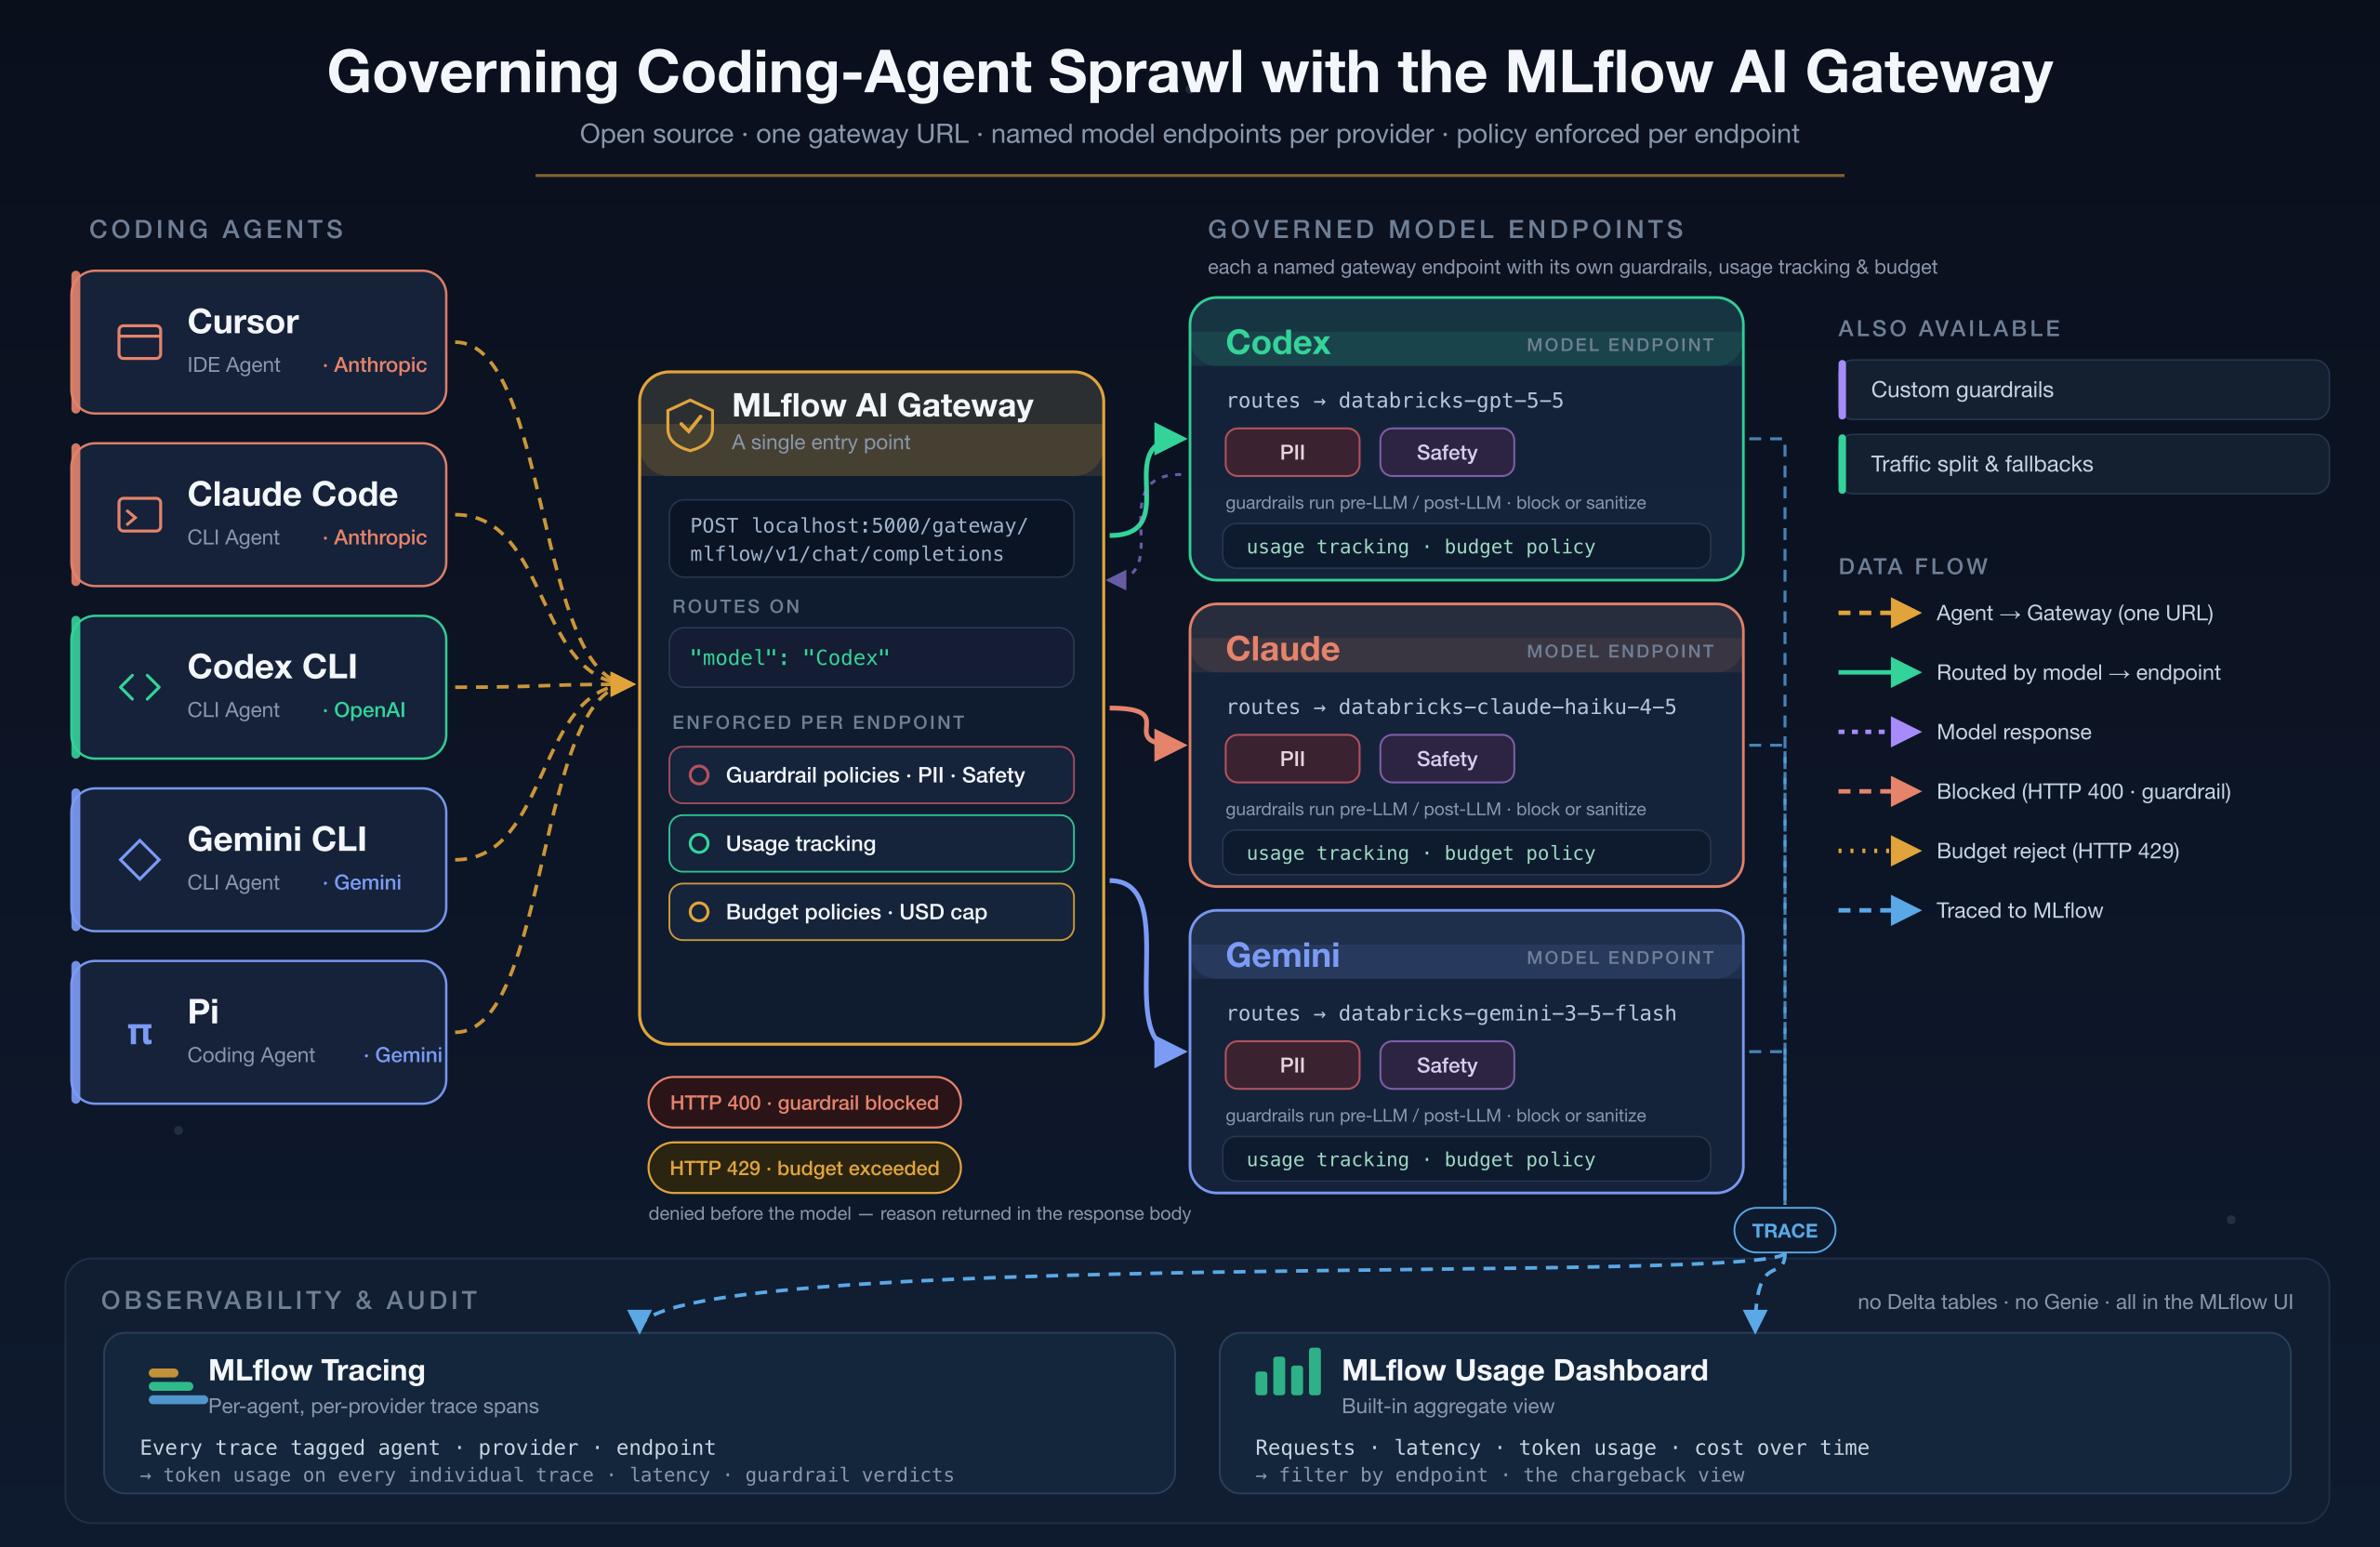
The MLflow AI Gateway puts one governed endpoint in front of all of them. It routes each request by endpoint name, runs it past PII and safety guardrails, caps spend with a budget policy, and traces every call with token counts and agent / provider / endpoint tags. This post walks the runnable demo on MLflow 3.17.1. The notebook runs in five acts: (View Highlight)
For a few resaons. First, the key you hand a tool tells you how much, never who. Your provider console will tell you what that key spent, cost of tokens on invoice, but it will not tell you which agent spent it, which developer was driving, or what went out in the prompt. Now, spread five agents across three providers and you get three dashboards that each answer a different question and none that answer yours. (View Highlight)
The second problem is that an agent stuck in a retry loop can burn hundreds of dollars of tokens overnight, and you find out when finance forwards the invoice. For instance, in my demo (see the notebook), one call in my own trace data cost $0.0141 for 533 tokens, which sounds like nothing until you multiply it by five agents running all day across a 40-person team. (View Highlight)
Third, data leakage is the cost you notice too late. A developer pastes a config file with a live credential into a prompt, or a test fixture carrying a customer SSN, and that data has now left your perimeter with no record it ever happened. You cannot grep for a thing you never logged, which is what a security review will press on. (View Highlight)
And finally, you want to protect against malicious content agents generating it. While each provider may have a way to mitigate it, there is no central place to manage or govern it. (View Highlight)
The MLflow AI Gateway is a governed endpoint that sits between your agents and the models they call. It runs inside mlflow server, routes each request based on the request’s model field, and enforces guardrails, budget policy, and tracing on every call. You point each agent at it once, and governance lives on the path instead of inside each tool. (View Highlight)
The demo notebook wires five agents to three endpoints, one per model family, all created in the MLflow UI. Cursor and Claude Code route to dbx-claude-endpoint, Codex CLI routes to dbx-codex-endpoint, and Gemini CLI plus Pi route to dbx-gemini-endpoint. The endpoint carries the guardrails, the usage tracking, and the budget policy, so the endpoint rather than the agent is the unit of governance. (View Highlight)
This demo notebook points at Databricks-hosted models. MLflow supports any provider connection you configure in the MLflow UI and behaves the same way, whether OpenAI, Anthropic, or Google, because the gateway normalizes them onto the OpenAI chat schema. That uniformity lets you reason about five agents at once, instead of five agents multiple times. (View Highlight)
You point each agent’s OpenAI-compatible client at the gateway URL and send the endpoint name as the model field. The gateway reads that field, forwards the request to the configured model, and returns the response on the schema the agent already speaks. Nothing else about the agent changes. (View Highlight)
Those last two arguments are not decoration. The OpenAI SDK defaults to a 600-second read timeout with two retries, so a gateway that accepts your connection and then never answers costs you 30 minutes per endpoint before it reports anything. I learned that by watching the verification cell sit there for 22 minutes. Set the timeout, and a misconfigured gateway tells you so in a minute. (View Highlight)
Notice the missing provider API key. The gateway holds provider credentials server-side in an LLM Connection, so a leaked client config no longer leaks a live model credential. (View Highlight)
That is attribution you did not have before. It is also your first hint that guardrails are not free: twelve seconds for a short coding answer is slow, because each request pays for the LLM judges enforcing them. Each judge call took 1.9 to 3.0 seconds in my spans, and three guardrails on an endpoint means paying that tax two or three times per request. (View Highlight)
The demo fires eight deliberately bad requests at the gateway. Six come back blocked with HTTP 400: three carry PII (an SSN in a code comment, a credit card in a variable, contact details in a .env), three are injection attempts, and two ask for harmful content. A block arrives as openai.BadRequestError with the judge’s reasoning in the body, so you are never guessing why. (View Highlight)
The DAN jailbreak aimed at Claude Code and the instruction-override prompt-leak aimed at Codex CLI both cleared the guardrail, and neither produced harmful output, because the models refused on their own: (View Highlight)
Treat the guardrail and the model’s own refusal as two independent controls. Guardrails are probabilistic because each one is an MLflow judge, the same scorer primitive you use for offline evaluations, now running inline on live traffic. The demo’s own numbers show it: 6 of 8 caught at the gateway, 2 of 8 caught by the model. (View Highlight)
You cap it with a budget policy on the endpoint, set to either Alert or Reject. Alert keeps serving and warns you. Reject refuses requests with HTTP 429 once cumulative spend crosses the cap. There is no per-minute rate limit here, and that is deliberate: the control is dollars, which is the number that shows up on the invoice. (View Highlight)
The cap applies to everything on that endpoint. Leave a 5-cent budget enabled and it will reject the earlier acts too, so turn it on just before the budget act and off again afterward. Because the budget lives on the endpoint, you set a limit per model family instead of trusting five separate tools to behave, which is the same reason the endpoint holds the guardrails. (View Highlight)
We started with five agents, five API keys, and an invoice nobody could explain. We end with one gateway that routes every agent, blocks most of the bad traffic with a 400, caps spend with a 429, and writes a trace for every call including the ones it refused. The agents did not change at all. The path they take did, and that path is now the one place where policy, cost, and the audit trail live. (View Highlight)
The MLflow AI Gateway is a central checkpoint, not a wall. On my runs it caught and rejected all malicious requests and allowed 5 clean ones. Read the rationales in the traces when something surprises you. (View Highlight)
 (View Highlight)